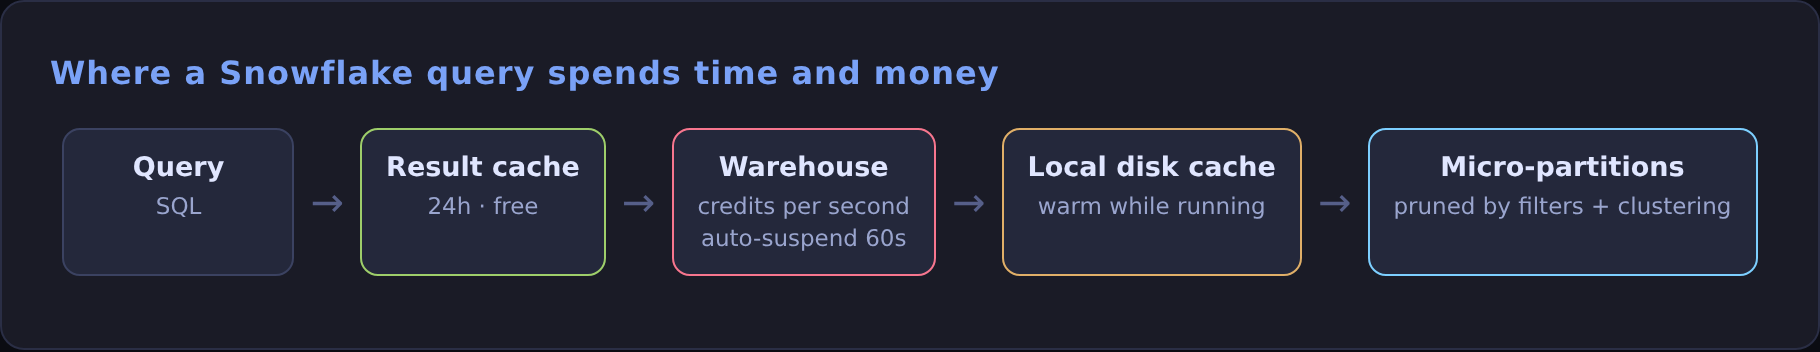
In Snowflake you pay for storage and for compute, and compute is almost always the bigger bill. Compute is billed per second while a virtual warehouse is running, with a 60-second minimum each time it starts. Most savings come from keeping warehouses the right size and off when idle.
Warehouses
Auto-suspend and auto-resume. Set a short auto-suspend for most workloads:
A warehouse left at a 10-minute suspend after every two-minute job spends most of its credits doing nothing.
Size up for speed, not as a habit. Each size step roughly doubles both the compute and the credits per hour. A query that scales well can finish in half the time on the next size up for about the same cost. One that doesn't scale just costs double, so check before you upsize.
Separate warehouses by workload. Keep ELT, BI dashboards and ad-hoc analysis on different warehouses, so one heavy job doesn't slow the CEO's dashboard and each cost is visible on its own.
Queries
- Select only the columns you need. Snowflake stores data by column, so
SELECT *on a wide table reads far more than it has to. - Filter on columns that prune well. Snowflake skips micro-partitions whose min/max range can't match your filter. Filtering on a date column that follows load order usually prunes well; wrapping it in a function (
WHERE TO_CHAR(created_at, 'YYYY') = '2026') can defeat pruning. - Read the Query Profile. Compare "Partitions scanned" with "Partitions total", and look for "Bytes spilled to local/remote storage". Spilling means the warehouse ran out of memory for that query.
- Watch for exploding joins. A join on a non-unique key multiplies rows. If the output is much larger than both inputs, the join keys are probably wrong.
Caching
- Result cache. An identical query on unchanged data returns the stored result without using a warehouse, for up to 24 hours.
- Warehouse cache. A running warehouse keeps recently read data on local disk. Suspending clears it, which is a fair trade for most batch jobs.
Clustering keys
Only for very large tables (multi-terabyte) where queries filter on the same columns and pruning is poor. Automatic clustering costs credits to maintain, so measure before and after.
Keep an eye on spend
Pair it with a resource monitor on each warehouse, so a runaway query hits a credit limit instead of the monthly bill.
Try it: three queries to run this week
When partitions_scanned is close to partitions_total on a big table, the filter isn't pruning. That's your cue to check the where clause or think about a clustering key.